Executive Summary
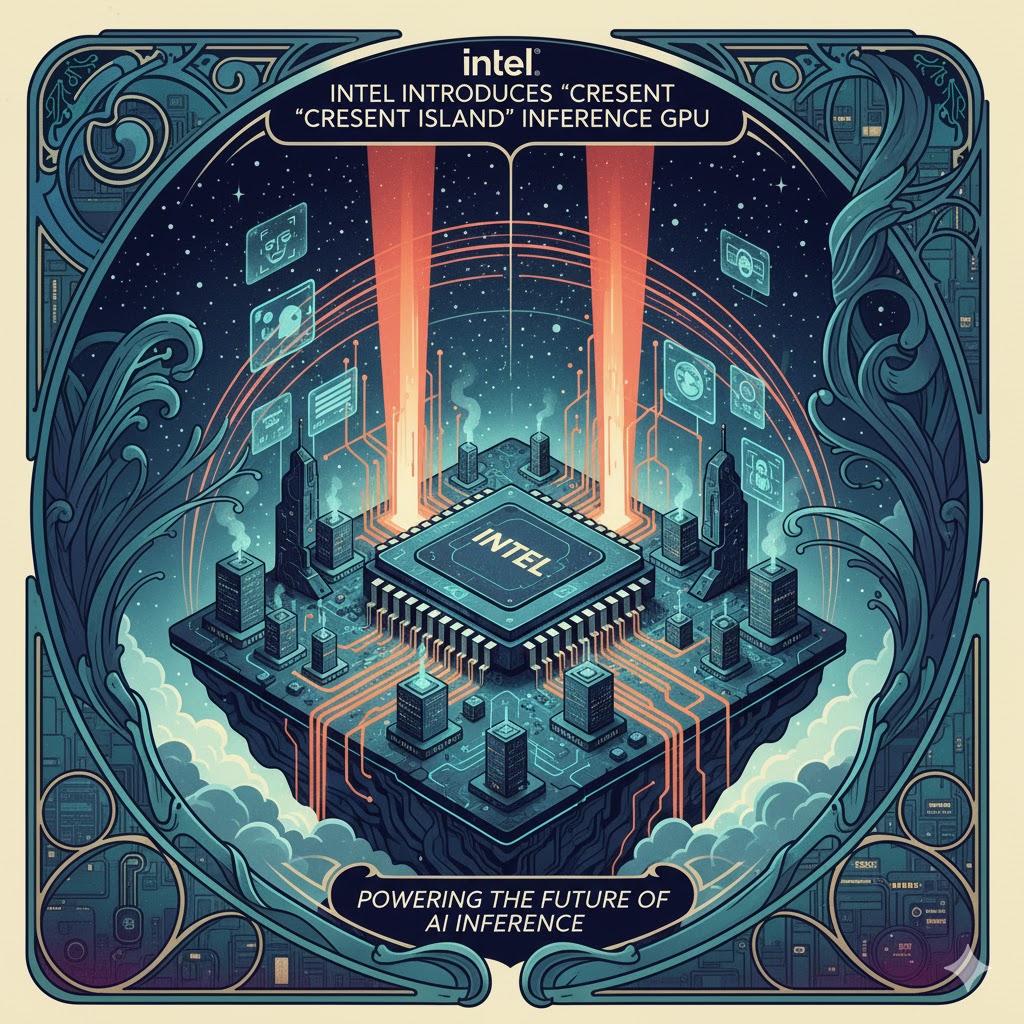
Intel’s new Crescent Island GPU targets inference workloads with Xe3P architecture and ultra-efficient design—signaling a pivot toward sustainable AI compute.

Get audio and creator gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Engineering for Inference
Crescent Island, built on Xe3P architecture, delivers 160 GB LPDDR5X memory and optimized tensor cores for quantized model performance. It prioritizes air-cooled energy efficiency, ideal for enterprise inference clusters.
Strategic Pivot
While Nvidia dominates training, Intel is betting on inference—the phase where models serve billions of real-time queries daily. Crescent Island aims to undercut high-end GPUs on cost-per-token metrics.
Deployment Roadmap
Sampling begins in late 2026, with production servers scheduled for early 2027. The GPU will anchor Intel’s expanded Gaudi platform for AI inference scaling.
Market Implications
This move strengthens Intel’s relevance in the post-training era, where efficiency and sustainability define competitive advantage.
Products Worth Considering

Bose SoundLink Plus Portable Bluetooth Speaker, Black

LG UltraGear 27GX704A-B 27-inch QHD OLED Gaming Monitor

DJI Mic 3 Wireless Microphone System (2 Transmitters, 1 Receiver, Charging Case)
As an affiliate, we earn on qualifying purchases.