🔍 Read the full analysis: Qwen4 Max’s Score Improves By Nine Points As Its Cost Falls on ThorstenMeyerAI.com

Get audio and creator gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
Artificial Analysis gave Alibaba’s Qwen4 Max an Intelligence Index score of 43, nine points above Qwen3.8 Max, and reported a cost of $3.27 per index task versus $10.02 for its predecessor. The result places Qwen4 Max above the comparable-model median cited by the evaluator, but ninth among 10 models on its page; launch-day speed data and a release date for open Qwen4 models were unavailable.
Alibaba’s Qwen4 Max scored 43 on Artificial Analysis’s Intelligence Index, nine points above its predecessor, while the evaluator’s estimated cost per index task fell from $10.02 to $3.27. The independent results, published on Nov. 16, show an improvement over Qwen3.8 Max but place the new model ninth among 10 models listed on its benchmark page.
Artificial Analysis says Qwen4 Max scored above the 41-point median for comparable models. Its ninth-place ranking on the page is a separate comparison: the highest-scoring model listed there received 65. The two figures describe different reference groups and do not make Qwen4 Max a top-ranked model overall.
The evaluator’s cost figure is for running one task in its Intelligence Index, not a fixed charge for every user request. Alibaba’s listed API rates are $1.50 per million input tokens and $4.50 per million output tokens. Actual spending depends on usage, including how many tokens a request and response use.
Alibaba also reported improved results and lower costs on its own tests. On its Work360 benchmark, the company said Qwen4 Max scored 52.69, up from 47.74 for Qwen3.8 Max, while average task cost dropped from $4.43 to $1.67. Those are vendor-reported figures, not independent measurements. The Work360 result and the Artificial Analysis index score come from different evaluations and should not be treated as directly comparable.
Qwen4 Max · launch day
From launch claim to independent check
Alibaba’s numbers come first. An outside measurement shows where the model actually lands.
- The launchAlibaba calls Qwen4 Max a 24/7 “teammate”, with 2.4 trillion parameters and a one-million-token context window.
- The vendor’s own testOn its in-house Work360 benchmark, Alibaba reports 52.69, up from 47.74 for Qwen3.8 Max.
- The independent indexArtificial Analysis scores it 43, up from 34 and just above the median of 41 for models at a similar price.
- What is still openThe top model on the same page scores 65. Speed is not measured yet, and the weights are closed.
Sources: Alibaba/Qwen launch blog, Nov 16, 2026 (vendor figures); Artificial Analysis, model pages for Qwen4 Max and Qwen3.8 Max (0902), retrieved Nov 16, 2026. Schematic scale; marker positions follow the index values.
Graphic: Powered by Thorsten Meyer AI
Lower Costs, Mixed Benchmark Standing
The reported cost drop could matter to developers and businesses that run models frequently: if similar workloads produce similar results, a lower per-task cost can make a model more practical for repeated use. But the benchmark’s cost estimate is tied to its own tasks and conditions, so it does not establish what every customer will pay or how much a switch would save in production.
The score increase also gives buyers an outside comparison with the previous Qwen flagship. At 43 points, Qwen4 Max is above Artificial Analysis’s cited median for comparable models, but its ninth-place position among the 10 models on its page shows that the gain does not put it near the top of that displayed ranking. The result offers evidence of progress, not proof of leadership across all uses.
Practical adoption may also depend on factors the first benchmark did not report. Artificial Analysis had no launch-day speed or latency figures. Those measures affect how quickly users get answers and how well a model fits interactive or time-sensitive applications.
Products Worth Considering

Amazon Kindle Scribe (16GB) with Premium Pen, Tungsten

Apple Watch Series 12 GPS 46mm Smartwatch
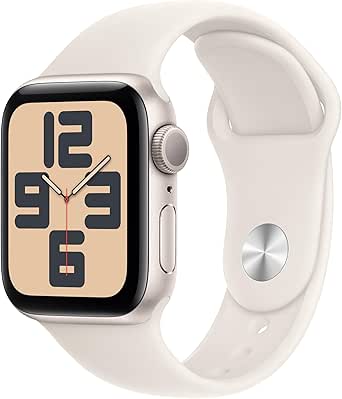
Apple Watch SE (2nd Generation) GPS 40mm Smartwatch with Starlight Aluminum Case and Starlight Sport Band (S/M)
As an affiliate, we earn on qualifying purchases.
Alibaba’s First Qwen4 Model
Alibaba introduced Qwen4 Max as the first model in its Qwen4 family. The launch material describes a 2.4-trillion-parameter backbone, 71 billion parameters activated per token and an additional 328 billion N-gram embedding parameters. Alibaba says the model can process text, images and video and generate text, and describes architectural changes intended to handle long inputs and support training.
These technical details come from Alibaba. Because the Max model’s weights are not publicly available, outside researchers cannot independently inspect the model or reproduce claims about its architecture and training. Alibaba describes Qwen4 Max as accessible through its QwenCloud API, Token Plan subscription and several company apps. It has not made the Max weights downloadable.
Artificial Analysis tested the model at its highest reasoning setting, xhigh. Alibaba’s API default is listed as high, so the evaluator’s result may not represent a default API configuration. The company says smaller Qwen4 models will be open-sourced, but the source material gives no release date.
Alibaba’s launch post also cites results from coding tests and company case studies, including claimed reductions in manufacturing programming time. Such figures are company-reported demonstrations, not controlled independent tests. The benchmark chart in Alibaba’s post was published as an image, and the source reporting did not independently reconstruct its values.
Speed, Weights and Real-World Costs
Several adoption questions remain open. Artificial Analysis reported no speed or latency data on launch day, leaving users without an independent basis to compare response times. The source material also does not establish how the benchmark’s cost per task translates to customer bills across different workloads or API settings.
Qwen4 Max’s weights are closed, so claims about its internals and training cannot be independently checked through access to the model. Alibaba says smaller Qwen4 models will be released as open source, but has not provided a date. Nor do the first benchmark results establish how the model will perform across all applications, languages or real-world operating conditions.
Alibaba’s reported Work360, coding and case-study results should be read as company claims unless independently reproduced. The available material does not provide enough detail to verify all of those comparisons or determine how consistently the claimed gains would carry over to customers’ own tasks.
More Tests and Release Details
The next useful evidence will be additional independent evaluations, particularly results that report speed, latency and task-level costs alongside quality. Comparisons using the same reasoning setting would also help clarify how Qwen4 Max performs under Alibaba’s default API configuration rather than the higher xhigh setting used by Artificial Analysis.
Developers and customers will also be watching for Alibaba to publish more detail about access, pricing and the planned smaller Qwen4 models. For now, the confirmed development is an early score improvement and a lower benchmark task-cost estimate; broader claims about commercial performance remain subject to testing.
Key Questions
What score did Qwen4 Max receive?
Artificial Analysis gave it 43 on its Intelligence Index. The score was nine points higher than the 34 recorded for Qwen3.8 Max (0902).
Does Qwen4 Max lead the models in the benchmark?
No. It ranked ninth among 10 models on its Artificial Analysis page. The evaluator also said its score was above the 41-point median for comparable models; that median is not the same as the full ranking.
How much did the benchmark task cost fall?
Artificial Analysis estimated $3.27 per index task for Qwen4 Max, compared with $10.02 for Qwen3.8 Max. Alibaba separately reported a decline from $4.43 to $1.67 per task on its own Work360 test.
Can developers download Qwen4 Max?
No. The source material says Qwen4 Max is closed-weight and available through Alibaba services, not as a downloadable model. Alibaba said smaller Qwen4 models would be open-sourced but did not give a date.
Are speed and latency known?
No launch-day figures were available from Artificial Analysis for speed or latency. Those results may be needed to judge how well the model fits interactive applications.
Source: ThorstenMeyerAI.com